Run Indexing Diagnostics Before Paying for Indexing Help
Before paying for indexing help, identify what Google has and hasn’t done with the specific URL. Check whether the page is meant to be indexed, whether Google can access it, whether a directive or canonical changes the intended outcome, and whether the URL has a clear discovery path. Only then decide whether a paid workflow addresses a real remaining need.
Summary
- Decide the intended indexing state of each URL first. A page that should stay out of Google’s results isn’t an indexing problem just because it’s absent.
- Diagnose URL by URL: record the current response and redirect path, review crawl restrictions and indexing directives, compare canonical signals, and confirm links and sitemap entries.
- Treat Google’s indexed information, live test, and indexing request as different things. A live test doesn’t prove inclusion, and a request doesn’t guarantee it.
Set the intended index status before treating a missing URL as a problem
Start by deciding whether each affected URL is supposed to appear in Google. Without that decision, an exclusion report or a missing result can look like a problem even when the URL is intentionally private, duplicate, retired, or otherwise not meant to be the preferred page in Search. The diagnostic approach in Jam’s guide to indexing gaps begins with the same useful distinction: define the intended outcome before interpreting a URL’s status.
Create a small working record for each URL. Include:
- The exact URL, preserving parameters when they change the content or its meaning.
- The page type and whether it is intended to be indexed.
- The canonical URL you expect Google to prefer.
- The person or team responsible for the page.
- Current evidence, including when each observation was captured.
Keep the intended outcome separate from what you observe. For example, “should be indexed” is a site decision; a recorded response status or canonical shown in a tool is evidence. They belong in the same record, but they don’t mean the same thing.
Before changing a template across the site, compare a small set of URLs: an affected page and an indexed page from the same template. Note whether they differ in response, access, directives, canonical signals, or discovery paths. A shared template can make a broad change tempting, but one missing URL doesn’t establish that every page using that template has the same issue.
Record a timestamp for evidence that can change. A current server response and Google’s information about a version it indexed earlier describe different moments. Keeping those observations distinct helps you avoid treating a past snapshot as proof of the page’s current condition.
Confirm the URL response, redirect path, and access conditions
Check the affected URL’s current response and follow its redirects to the final destination. The goal is to establish what a request for that exact URL reaches now, not to infer the cause from a missing search result. As Jam’s diagnostic guidance emphasizes, an absent result alone doesn’t explain whether the issue is discovery, access, crawling, or another condition.
Record the current response status, each redirect destination, and the final URL. If the URL redirects, follow the complete chain and inspect the final page. Then ask whether that destination is the page you intended users and search engines to reach. If it’s an intentional replacement, check whether links on your site point to the replacement where appropriate. If it’s not intended, correct the redirect or the link that leads to it, then repeat the check to verify that the final destination matches the intended outcome.
If the page appears inaccessible or unstable, record the conditions associated with the failure and review relevant server logs where applicable. Repeat the affected request conditions and compare them with later crawl evidence. Don’t convert a single failure, a search-result absence, or a URL’s response status into a cause without supporting evidence. A response and a Google indexing state are different observations.
Also keep the tested URL and the final destination separate in your notes. If a redirect is present, a check of the destination alone doesn’t tell you whether the original URL still redirects as intended. Follow the whole path, write down where it ends, and verify both the route and the final page.
Distinguish robots.txt crawl restrictions from noindex directives
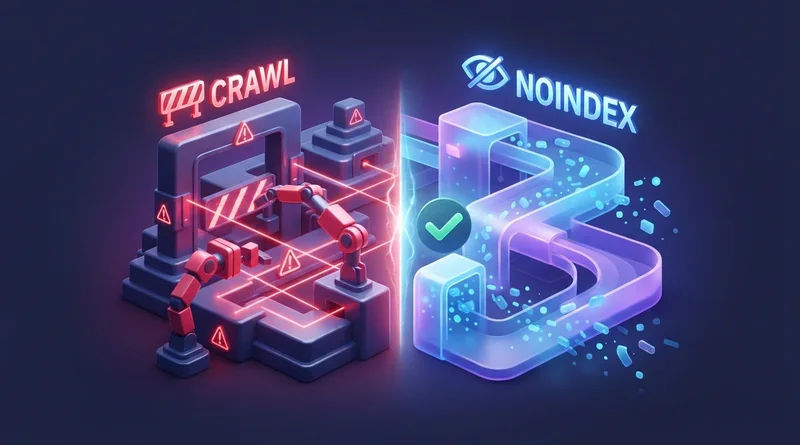
Check the applicable robots.txt rule, the page’s HTML, and the response’s X-Robots-Tag header. These checks answer different questions: robots restrictions affect crawling, while noindex affects indexing when Google can fetch and read the directive. If access is blocked, Google may be unable to see a noindex directive on the page. Jam’s indexing diagnosis guide
recommends keeping these mechanisms separate rather than treating them as interchangeable.
For the affected URL, work through the evidence:
robots.txt rule and determine whether it restricts crawling of the URL.noindex directive.X-Robots-Tag response header for a noindex directive.If the page should be indexed but a directive says otherwise, confirm that the directive is unintended before changing it. If you remove or change a directive, repeat the check against the page and response to verify that the old instruction is no longer being served. Separately confirm whether the page can be fetched when Google needs to read any remaining directive.
If a crawl restriction is present, check whether it is intentional for that URL and whether it prevents access to information Google needs to evaluate. Don’t assume that a crawl block removes a known URL from Search. And don’t add a noindex instruction while also blocking the page in a way that prevents Google from reading it. The diagnostic question is not merely “is there a restriction?” but “what does this rule do, and can Google access the instruction it needs to see?”
Record each mechanism separately. That makes it easier to verify a specific correction and avoids changing multiple controls when the evidence only identifies one.
Compare the declared canonical with Google’s selected canonical
Identify the preferred URL among duplicate or very similar pages, then compare your site’s declared canonical with Google’s selected canonical when that information is available. A canonical is a signal about which version you prefer; it isn’t an indexing command. Jam’s guide advises checking for inconsistent signals and not pointing an unrelated page to the homepage to remove it from a report.
Start with the exact URL in your record. Find the canonical declaration the page serves, then write down the URL it names. Compare that with the page you intended to be preferred. If the page has a close duplicate, check whether the canonical points to that intended version. Similar-looking paths alone don’t establish that two pages are duplicates, so don’t combine distinct pages without evidence that they represent the same or very similar content.
Compare the declared canonical with the page you intended to be preferred. If other evidence shows that Google selected a different version, record both URLs and look for conflicting signals. For example, a canonical declaration that points one way and other site signals that point another way can make the preference unclear. Investigate the actual URLs and signals before changing anything.
If the declaration is wrong, correct it to the intended relevant version, then verify that the page serves the updated canonical. If the pages are distinct, don’t point one at the other just to consolidate a report. If Google selected a different version, record that result as evidence of its selection—not as proof of why it made that choice.
Keep the three observations distinct in your record: the site’s intended canonical, the declared canonical, and Google’s selected canonical. That comparison helps identify where the disagreement lies without turning a signal into a guarantee.
Trace discovery through accessible links and sitemap entries
For the intended URL, establish whether it has a crawlable incoming link from an accessible page and whether the intended canonical appears in the sitemap. Then verify that the link and sitemap entry are actually served as intended. Jam’s diagnostic workflow recommends collecting evidence on incoming links, sitemap inclusion, and URL Inspection information when a URL has no clear discovery path.
Check the link from the page that contains it: confirm that it points to the intended URL and that the source page is accessible. Next, check the sitemap entry and confirm that it lists the intended canonical rather than a different, redirected, or unintended version. Record what you find and the time of the check. If you correct either item, verify the link or entry again after the change.
Keep discovery evidence separate from a live fetch. A tool fetching a page successfully shows that the page can be fetched under those test conditions; it doesn’t establish that Google found the URL through a link or sitemap. Google’s URL Inspection tool documentation says its live URL test does not check for the URL in sitemaps or referring pages. So a successful live test cannot answer whether the URL has a clear discovery path.
Likewise, a sitemap entry or link is evidence of a path you have provided, not proof that Google has crawled or indexed the URL. Verify that the path is served, then observe later Google activity separately. If the URL has no accessible incoming link and no appropriate sitemap entry, correct the confirmed gap and check that the updated path is present. Don’t infer that discovery or indexing has occurred just because the site now provides a route.
Use URL Inspection to separate live access from indexed status
For a property you control, compare URL Inspection’s indexed-version information with its live test. The indexed information describes Google’s most recently indexed version; the live test fetches and examines the current page. Neither result should be substituted for the other. The URL Inspection tool documentation also makes clear that the live test doesn’t check sitemap or referring-page discovery.
Use the indexed information to understand what Google last recorded about the URL. The page may have changed or become unavailable since then, so treat that information as a snapshot, not a live check. Use the live test to investigate the current page and potential indexing issues. If the two results differ, record the difference and check the underlying evidence: current response, directives, canonical, and discovery path.
For a property you control, URL Inspection provides information about the indexed version and lets you test the live page. For a URL outside a property you control, don’t claim certainty about its Google status from URL Inspection. A search query or a site: result can offer an indication, but it isn’t definitive proof of full index coverage.
Hypothetical example—not a performed test: Assume the URL is https://example.com/guides/blue-widget, the site owner expects that page to be indexed, and the expected canonical is the same URL. These are assumed inputs, not observations. If the owner controls the relevant property, they can inspect the URL and compare the most recently indexed information with the live test. If the live test identifies a current access or directive issue, the next action is to investigate and correct that confirmed issue, then run a live test again to check the current page. If other evidence establishes that Google selected a different canonical, compare that selection with the site’s declared canonical and other signals before changing them. After any correction, use URL Inspection again to check the relevant evidence; don’t describe a successful live test as proof that the URL entered the index.
You can request indexing for an inspected URL, but a request is not a guarantee of inclusion. Treat it as a request for Google to revisit the URL, not as evidence that the URL was included. Check progress in the tool rather than treating the request itself as proof of inclusion.
Finish the diagnostics before deciding whether to pay
Decide whether a specific, unresolved need remains after you’ve confirmed and corrected the issues supported by your evidence. A paid workflow is worth considering only in relation to that need and its current terms—not as a substitute for knowing whether the page is accessible, correctly directed, canonicalized, and discoverable.
Before making that decision, summarize what the record confirms:
- Is the URL meant to be indexed?
- What response and redirect path does it currently serve?
- Can Google access the page and read its indexing directives?
- Does the declared canonical match the intended version, and what selected canonical is available?
- Is there an accessible incoming link and an appropriate sitemap entry?
- What does URL Inspection say about the indexed version and the live page?
Also write down what remains unknown. A missing search result alone doesn’t identify a cause, and a live test doesn’t prove index inclusion. A request through Google’s own workflow doesn’t guarantee inclusion either. Jam’s guide to diagnosing indexing gaps supports URL-level diagnosis before considering a paid workflow; the available evidence here doesn’t establish current provider prices, terms, comparative performance, or that any service will produce indexing.
If you still consider paying, compare the offer’s current terms with the specific unresolved task you have identified. Don’t infer a commercial outcome from Google’s request process, and don’t purchase on the assumption that a service can guarantee inclusion. The useful decision comes after the diagnosis: pay only if the proposed workflow fits a defined need that remains after the evidence-based checks.
Page Indexing vs Backlink Indexing: What to Submit→Article updated on October 29, 2026.